Reddit Data Analysis
Project overview
Large scale data analysis on user generated reddit data that I did for my research paper.
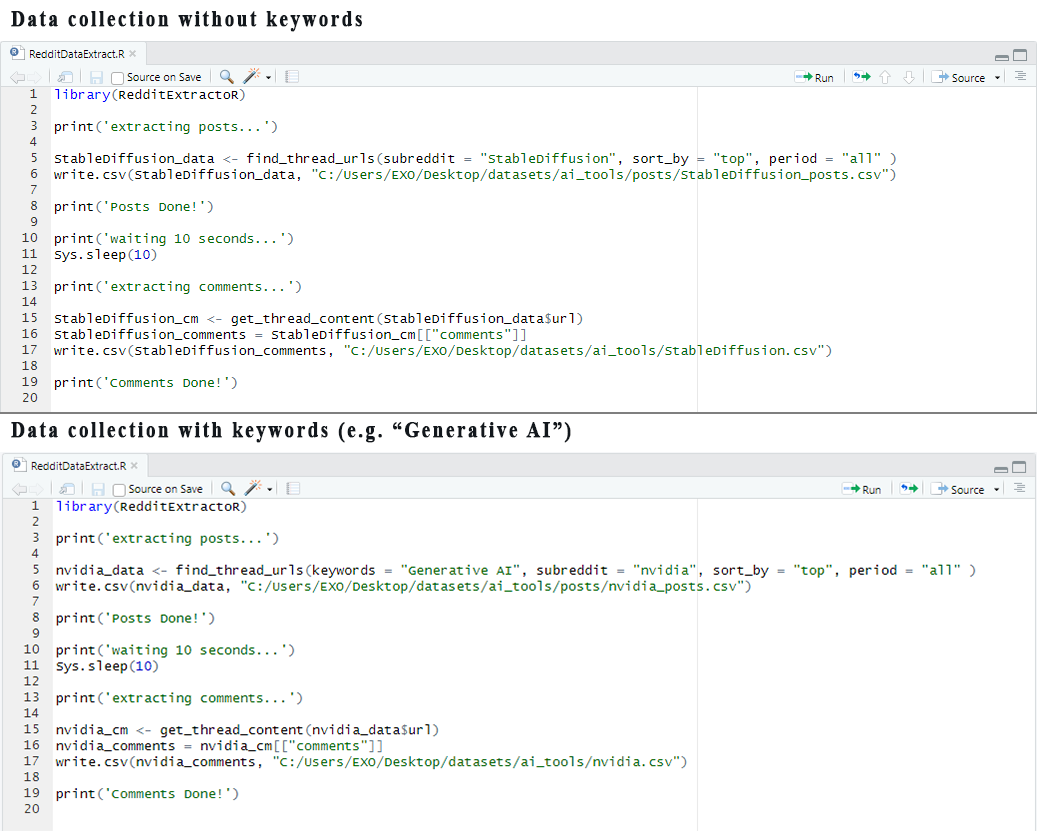
Reddit data were scraped and organized into structured csv files using R programming language.
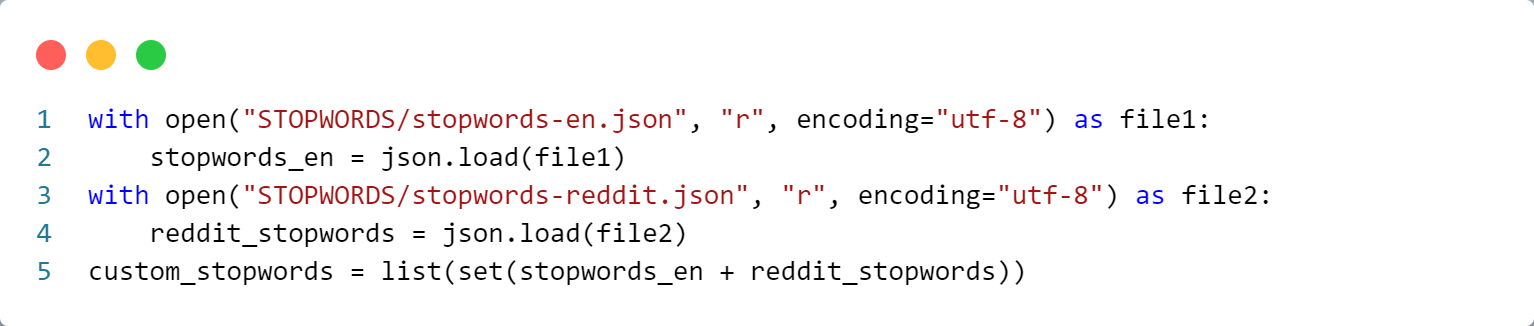
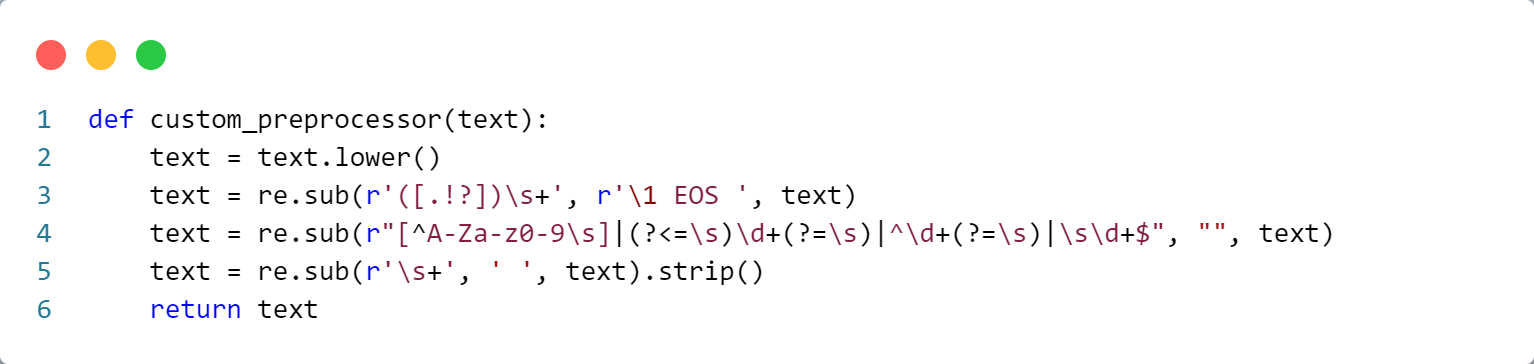
First pass preprocessing and data cleaning for reddit specific noises and markdown symbols was carried out using pandas and regex which led to 1.3 million posts and comments.
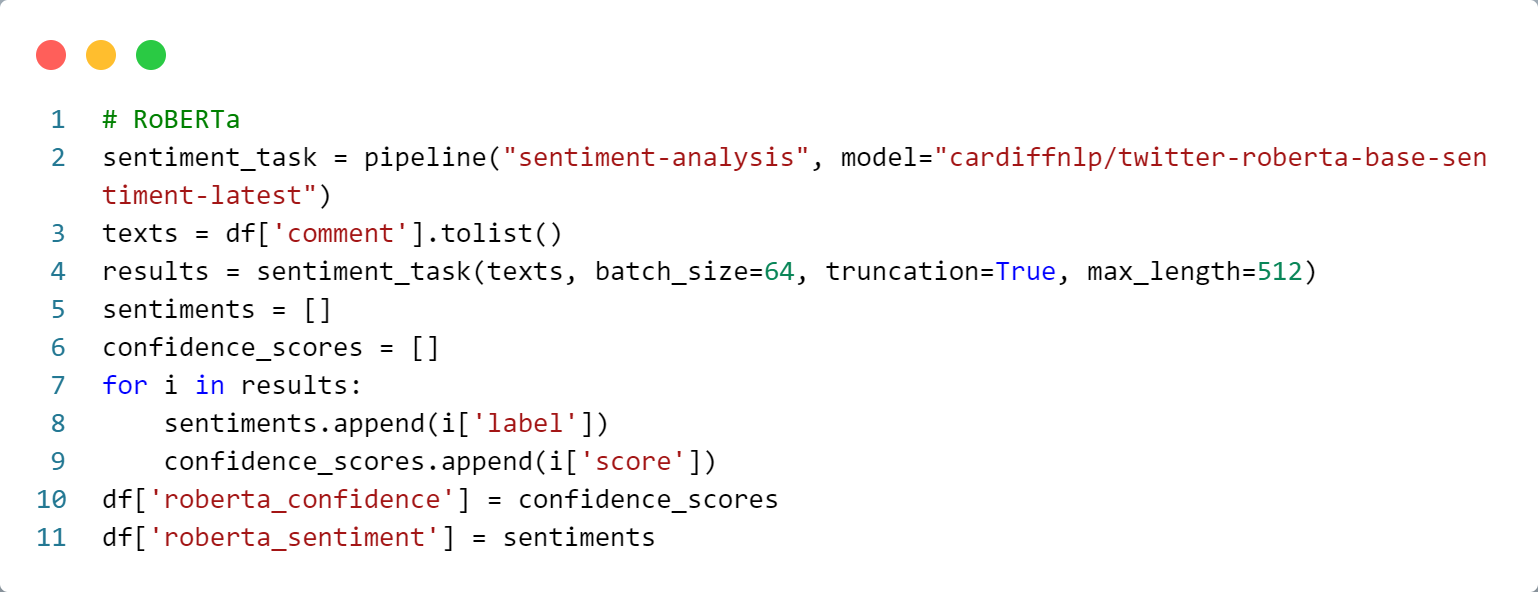
Sentiment analysis was conducted via huggingface transformers with a custom trained RoBERTa-base sentiment classification model.
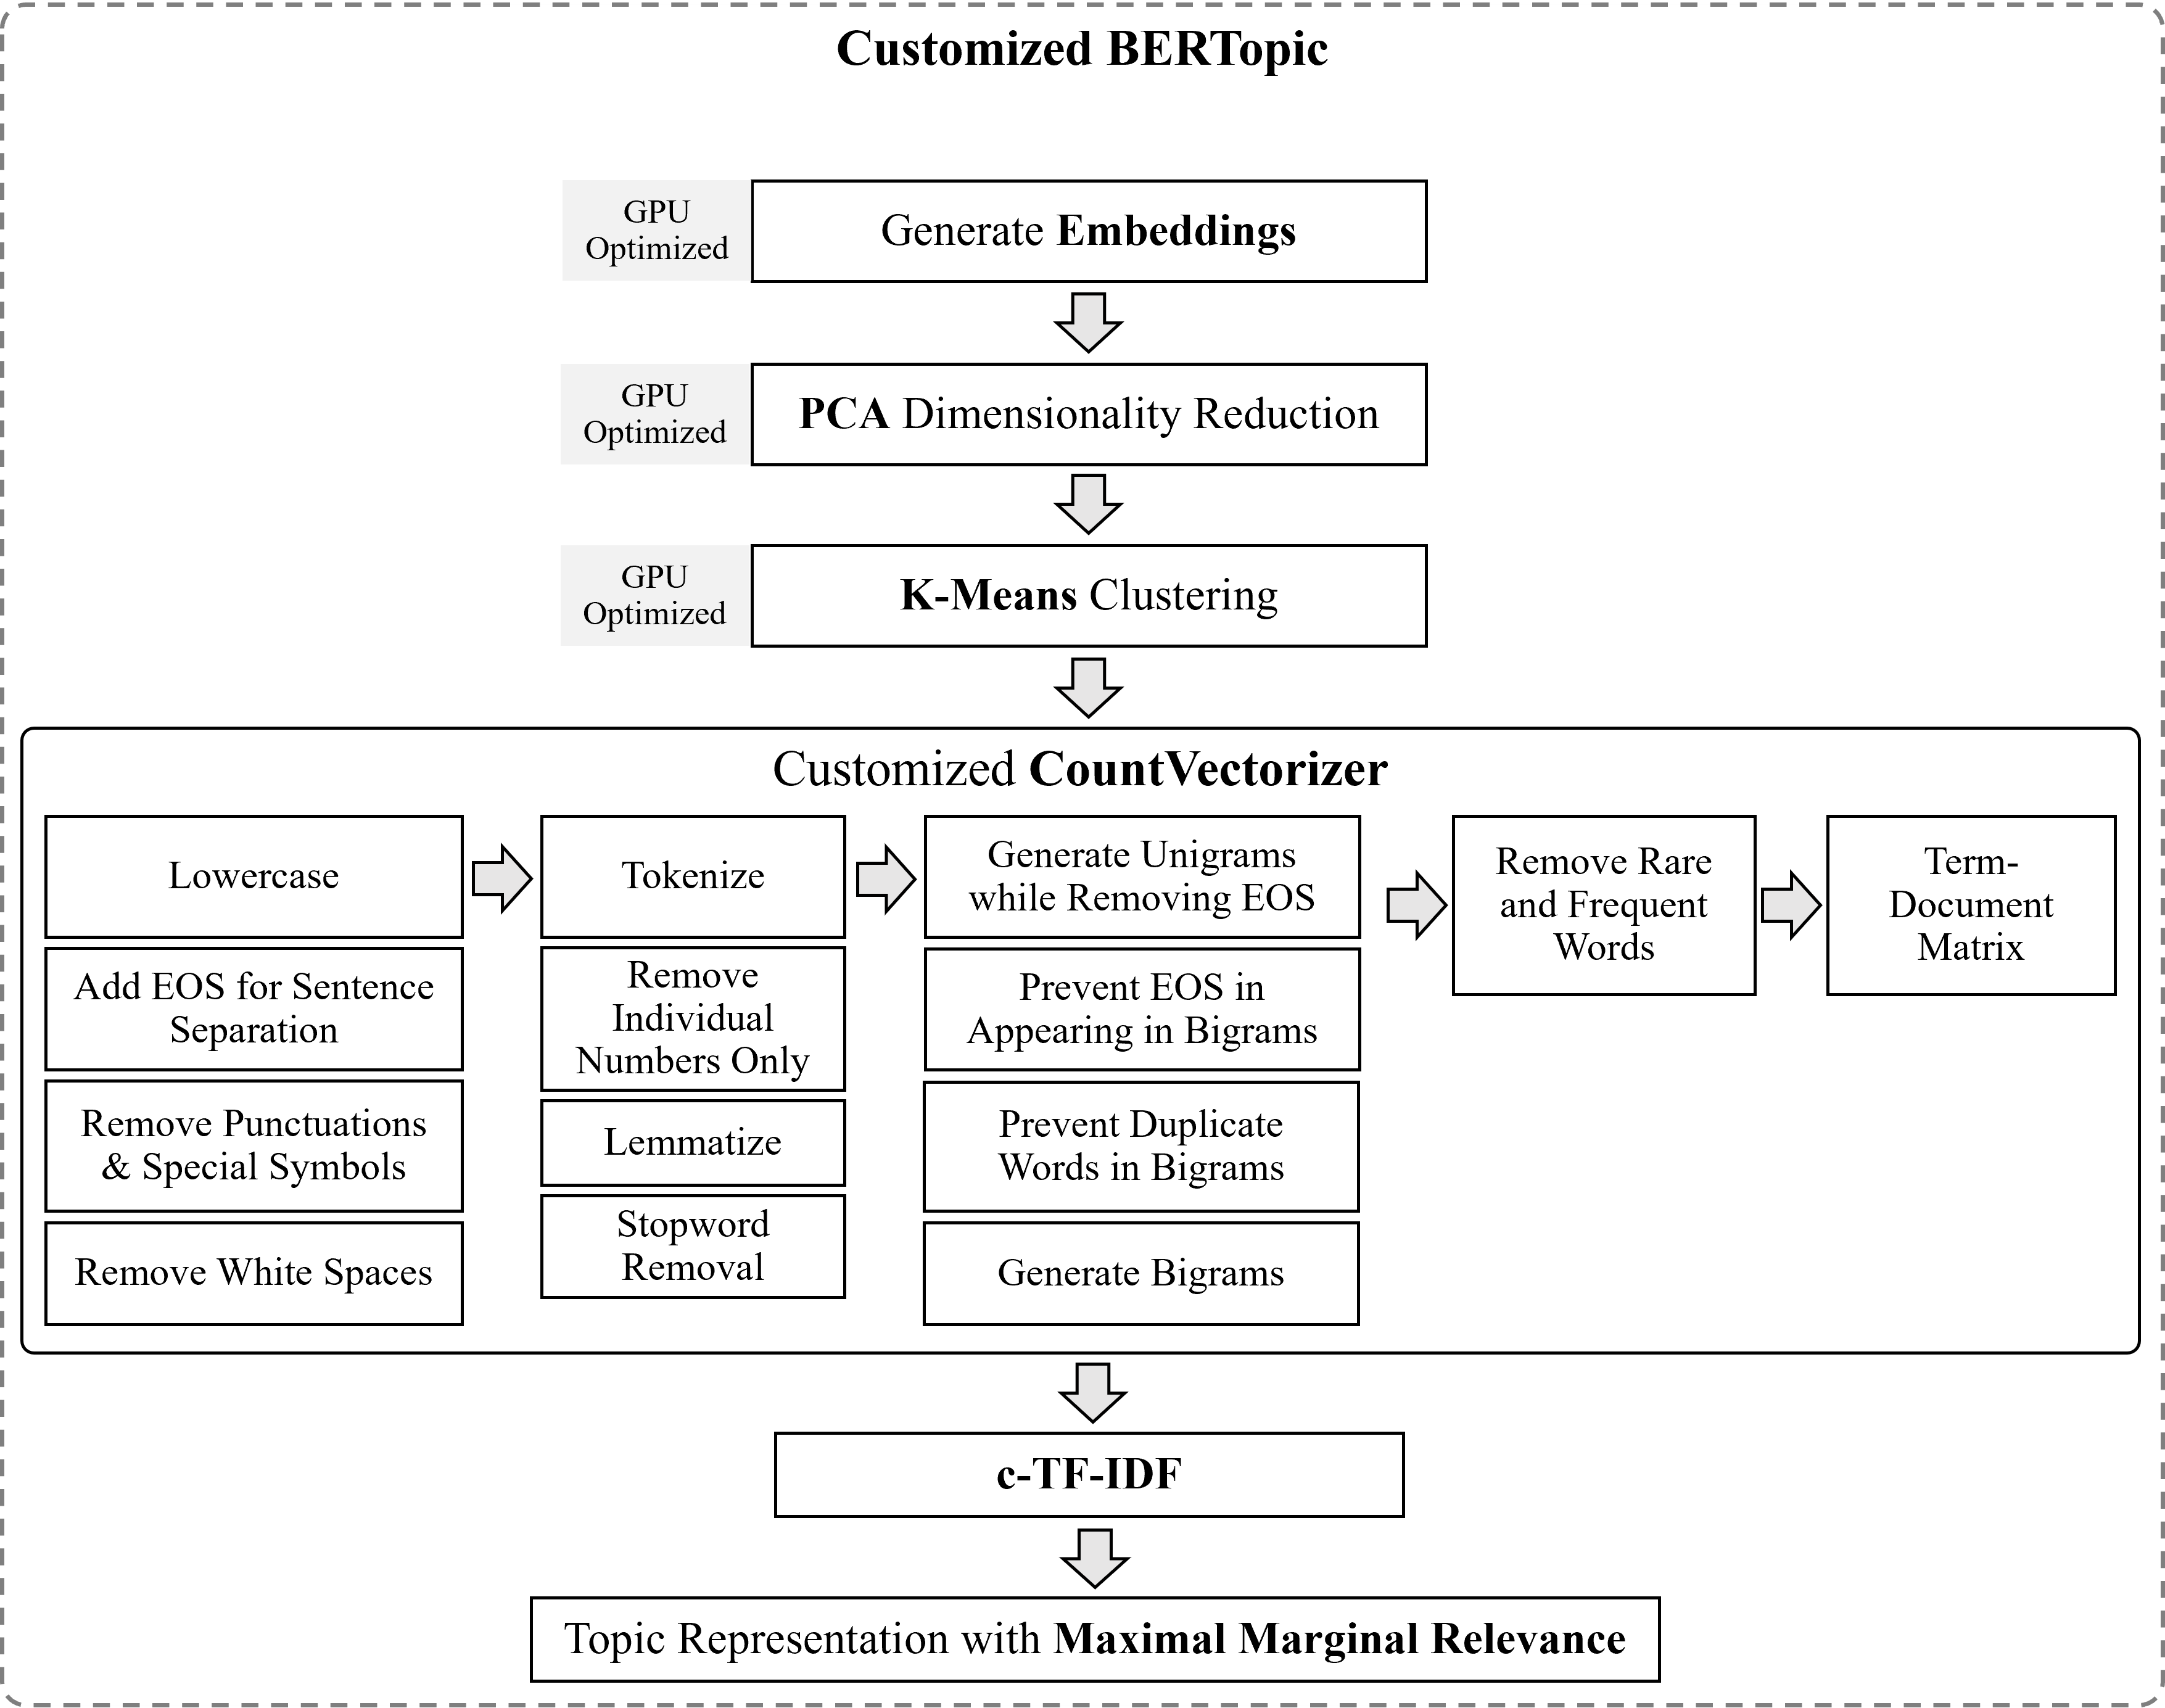
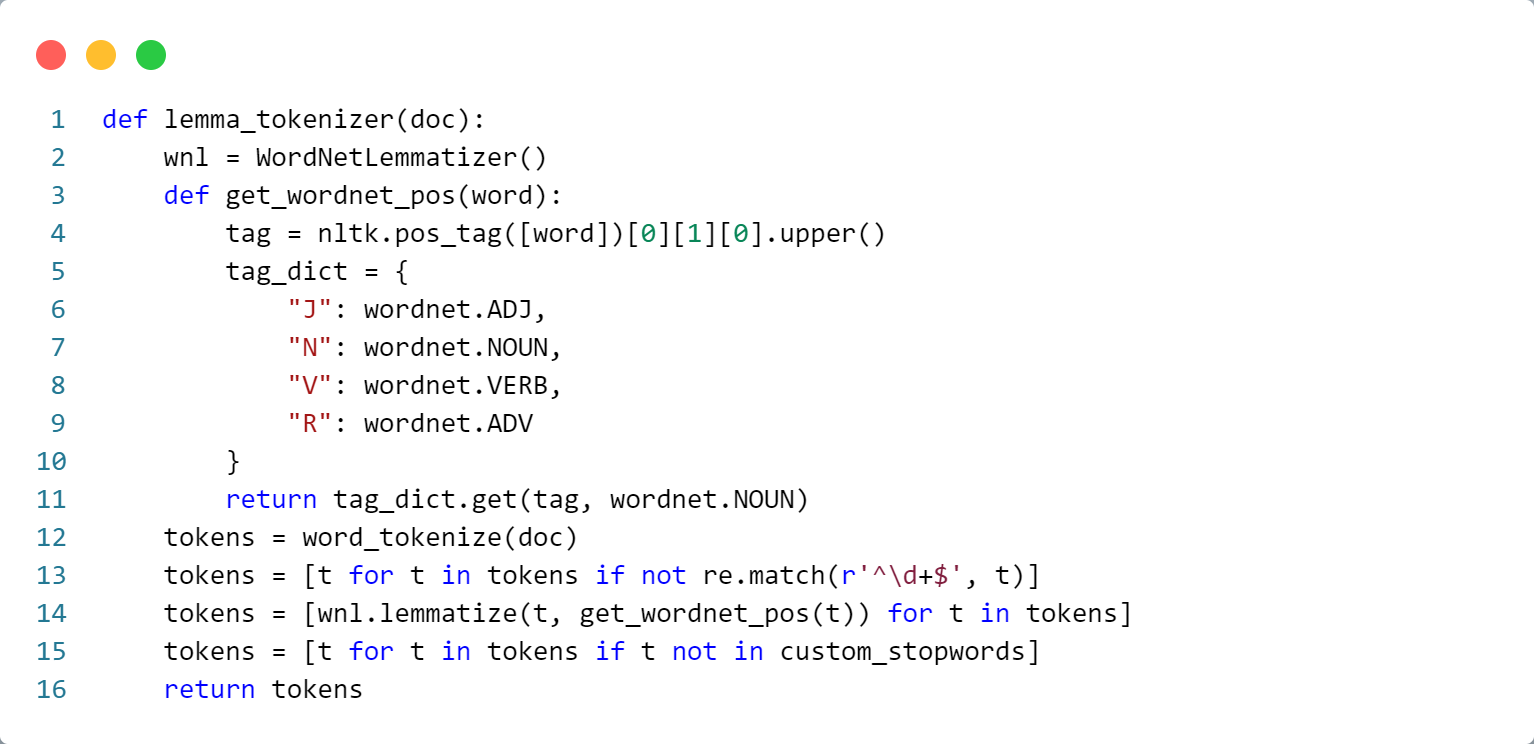
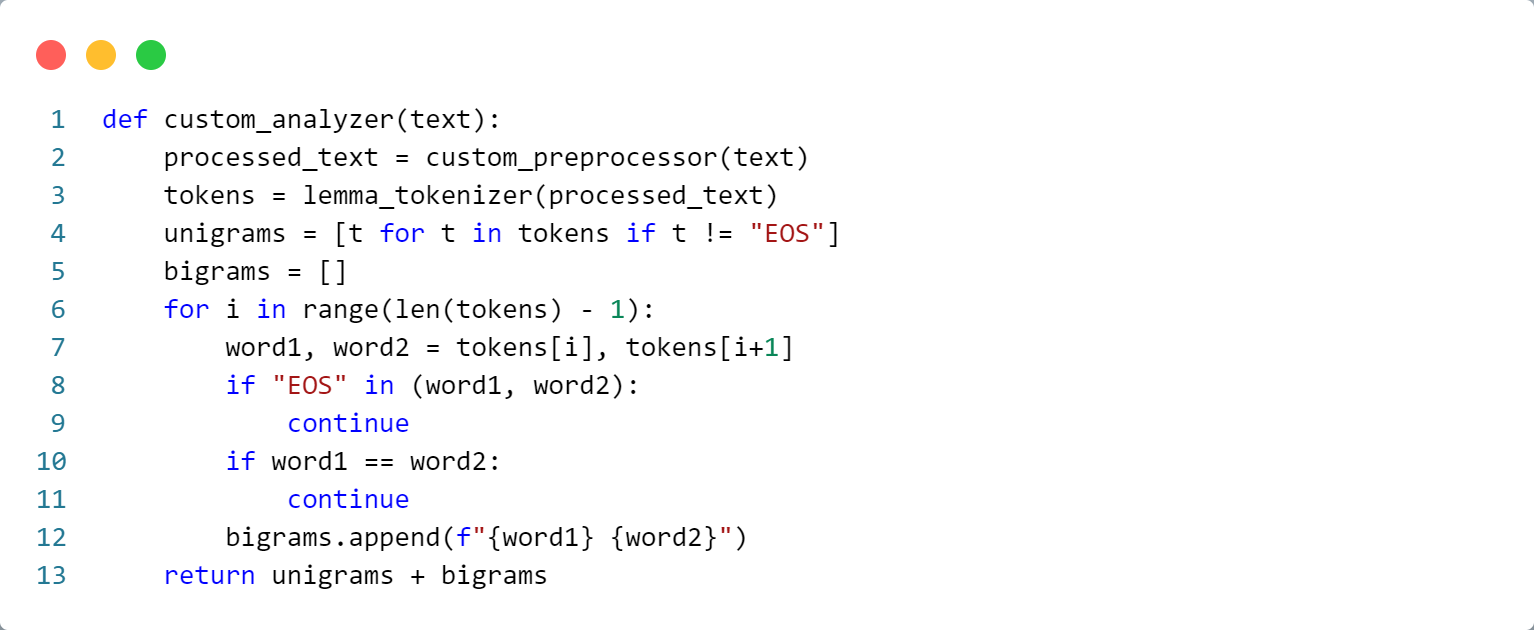
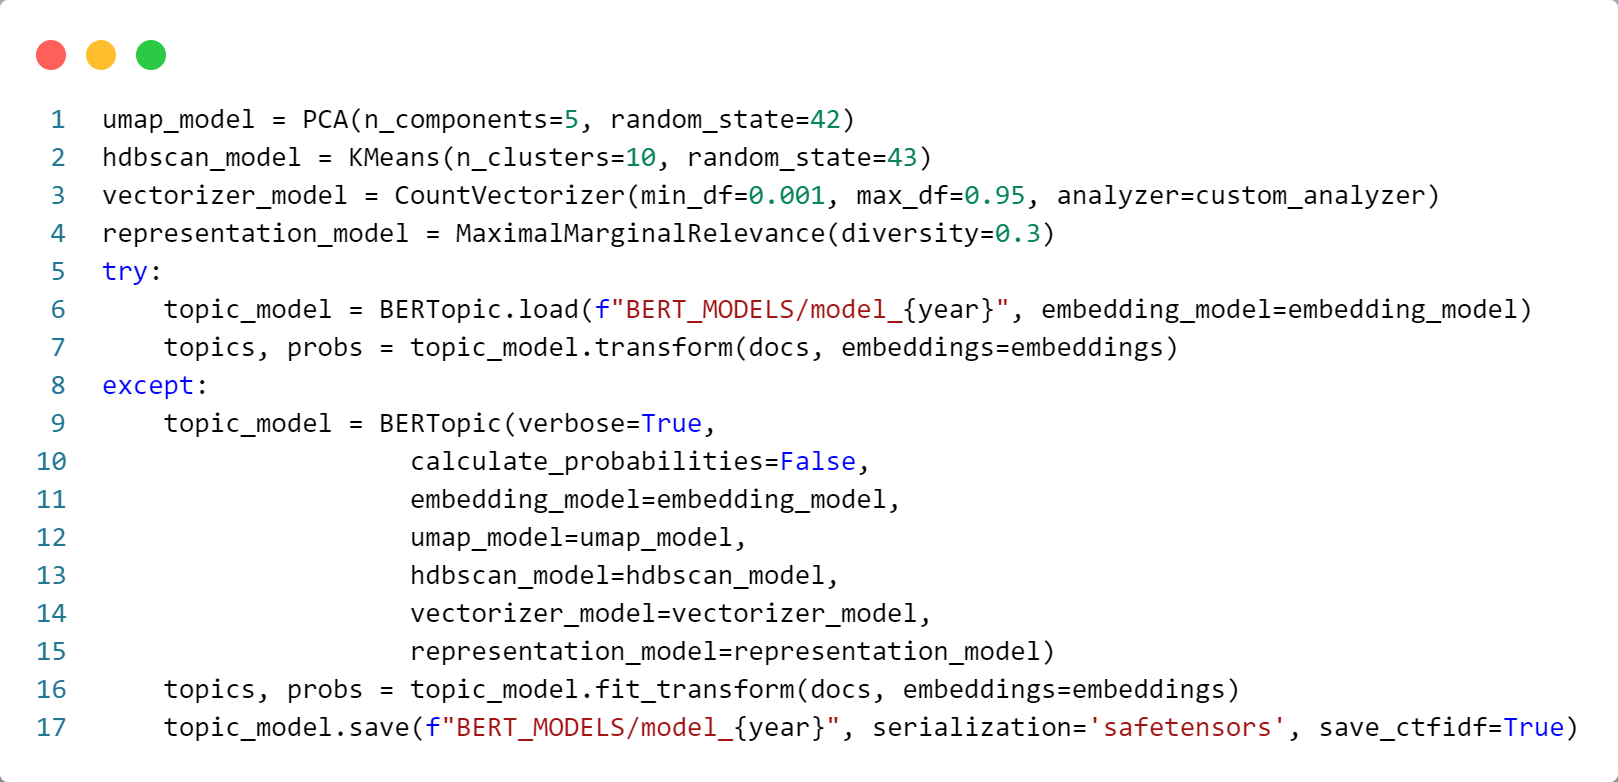
BERTopic was used for topic modeling. due to modular nature of BERTopic, I was able to break it apart and customize each step of the process. I managed to get more semantic top words in each topic with a customized CountVectorizer (second pass preprocessing) to optimize bigrams.
Analyzing this large volume of data with regular cpu based machine learning libraries was extremely time consuming. so I used GPU powered machine learning algorithms powered by nvidia RAPIDS (cuML) to overcome this limitation. I also had to do the whole thing on WSL (Ubuntu) as nvidia RAPIDS libraries didn’t work on windows and required a linux environment.
Challenges
- GPU optimization and analysis of large volume of data
- Managing python dependencies and package conflicts
- Using linux environment via WSL for the first time
- breaking bertopic apart to optimize the process and use other non-default algorithms that better fit my dataset